
Immediate problem: what’s actually at risk?
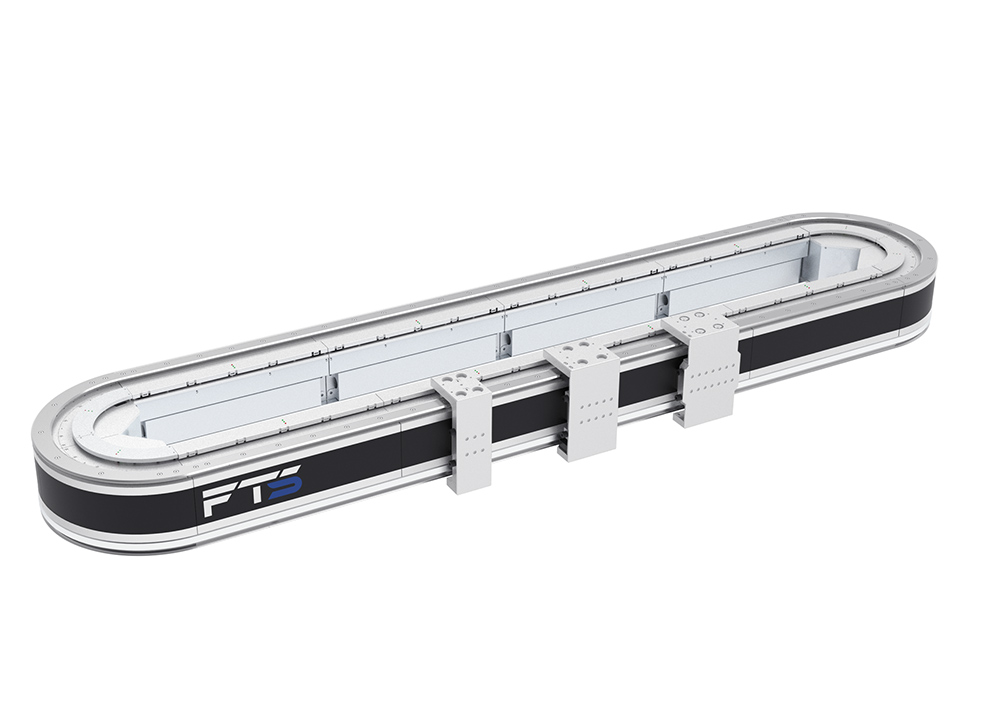
Teams often start with tech choices before they know what they’re protecting. That’s backwards. If a line mixes human packers, autonomous tugs, and a legacy belt, you need to map hazards first — and that’s where an intelligent conveyor system can change the attack plan. Think of the core challenge as matching control logic to real worker movement and material flow; that match fails most often when people assume a single solution like a flexible transport system will solve both throughput and safety without redesign.
Top problem-driven questions to force clarity
Ask these with a whiteboard and a safety engineer present:- Who occupies each work envelope and how often do they interact with autonomous equipment? State frequency and tasks.- What failure modes does each actuator and sensor create, and what human injury would follow? Quantify consequences.- Which standards apply (ISO 12100, ISO 13849, UNECE R155 where relevant)? List the clause numbers you must meet.- How will functional safety be proven — simulation, hardware-in-the-loop, or live trials? Define pass/fail metrics.
Compliance steps that actually reduce risk
Don’t over-document; do what’s verifiable.- Hazard analysis: create a layered map—people, parts, power, and control systems.- Risk reduction: start with engineering controls (guards, speed limits), then add safety-rated control systems and finally administrative controls with training.- Verification: run repeatable tests that cover faults, degraded modes, and recovery. Record results in versioned test logs.
Common pitfalls teams hit
Most mistakes are predictable:- Treating SDK demos as safety validation.- Relying on a single vendor test rather than independent verification.- Ignoring rare but high-consequence faults (e.g., power loss during a handover).- Assuming software updates won’t change safety behavior — they will.
Testing and validation: practical sequence
Follow this order so tests build confidence:- Unit-level checks: sensor noise, actuator backlash, and watchdog timers.- Integration tests: motion coordination, emergency stop propagation, and network latency under load.- Scenario tests: human-machine interaction cases, blocked-path responses, and brownout recovery.- Field acceptance: run defined shift-long trials and capture near-miss data and operator feedback.
Picking tech and vendors without being sold
Compare vendors by what matters to safety, not swag:- Evidence of safety: third-party certificates, SIL/PLe reports, and test artifacts.- Update policy: how they patch safety-related firmware and whether updates require re-certification.- Interoperability: can their control interface integrate with your MES and safety PLC?- Support model: local support and on-site commissioning matter more than remote demos.
A real-world anchor and what it taught me
On a 24/7 e-commerce distribution center project in New Jersey, we found small timing mismatches between autonomous tugs and manual pick stations caused most incidents. The fix wasn’t more sensors — it was tighter state transitions, a visible status panel at each station, and clear crew procedures. That hands-on lesson shapes the checklist above: control logic, human signaling, and procedural discipline beat feature lists.
Wrap-up: what teams should do next
If the problem is unclear, nothing else will stick. Start by naming the hazards, assign measurable acceptance criteria, and require independent verification for any change that affects safety. These steps deliver predictable outcomes and let you pick the right architecture for robotic lanes or a modular conveyor layout without guesswork. The practical value comes from applied, testable standards and repeatable field trials — the same approach our clients rely on when they consult with FHS.