
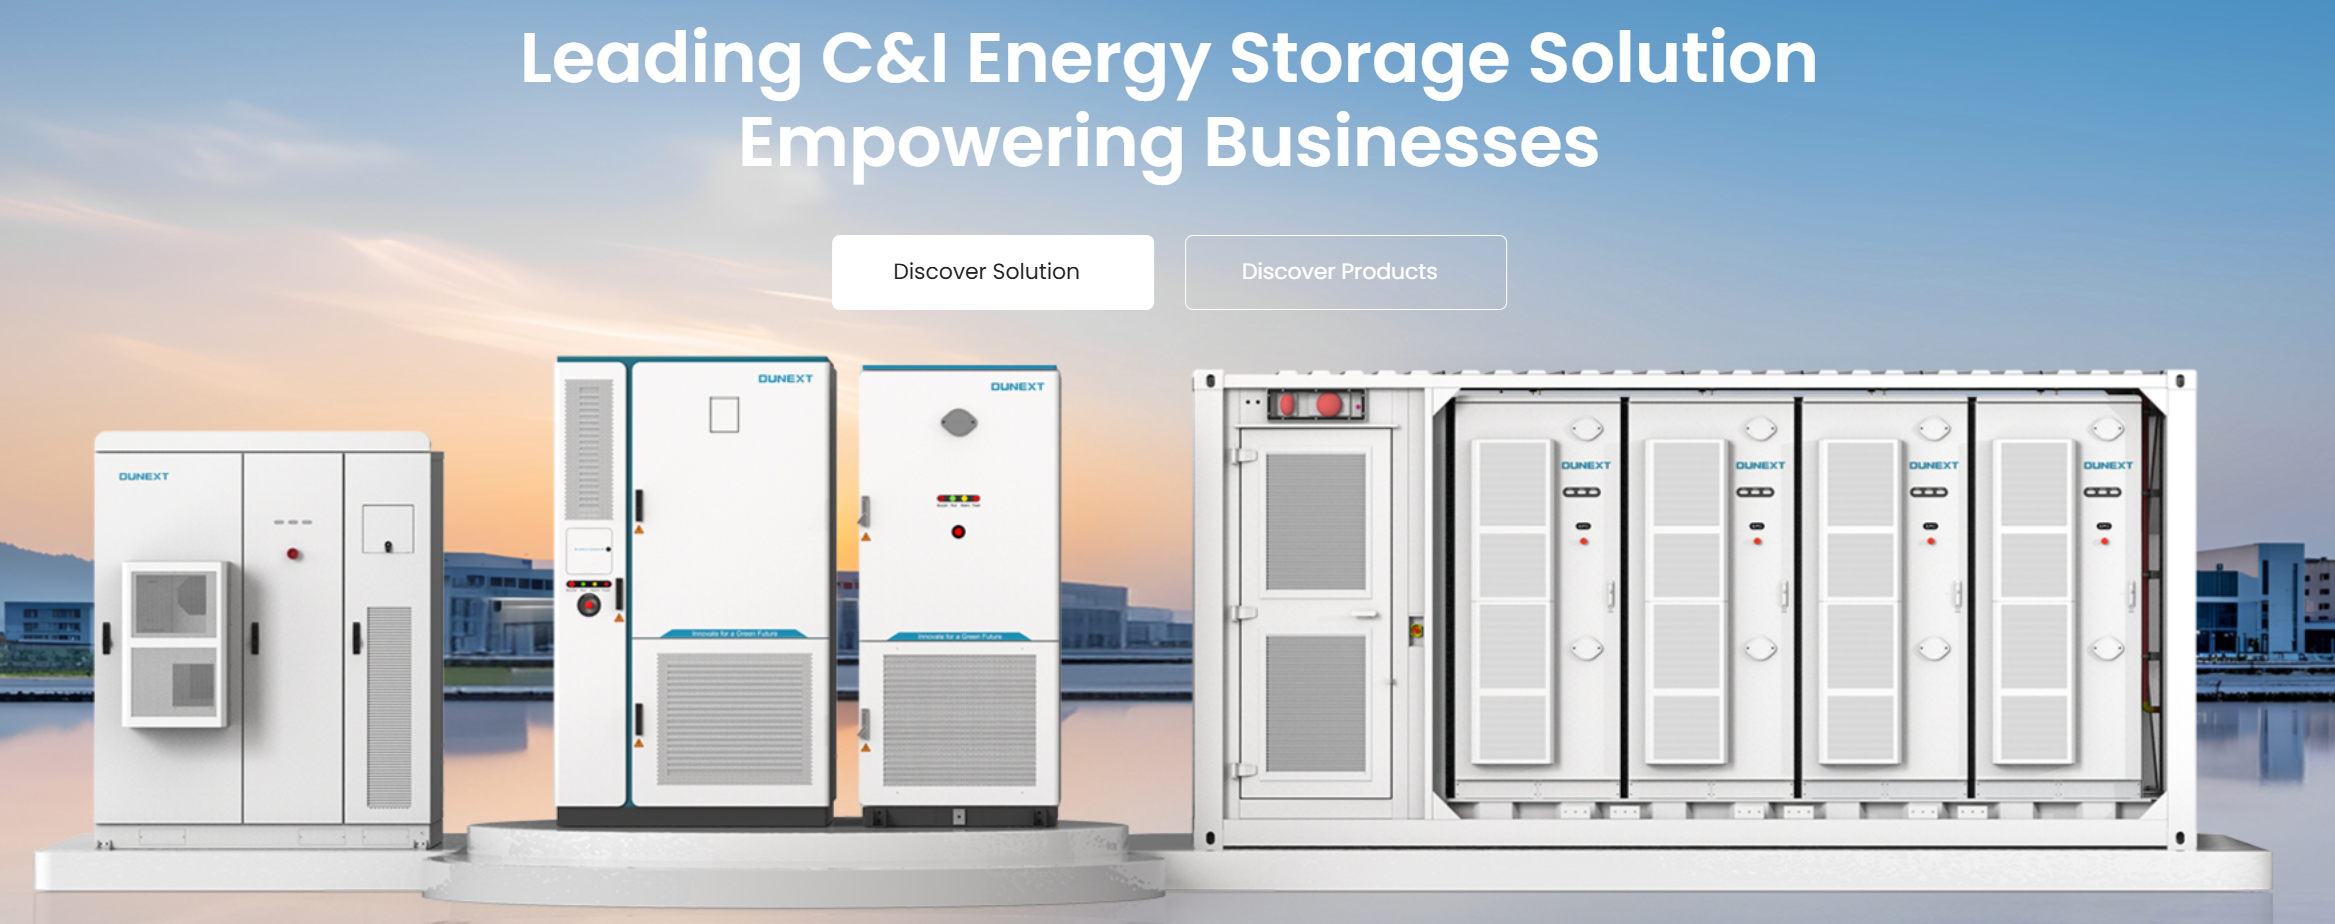
Immediate problem: backup systems that don’t behave like backup
Power goes out, automated transfer switches flip, and an apparently robust energy stack fails to hold voltage or drops offline under load. That’s the gap buyers face: lab-rated specs that don’t map to real-world resiliency. If you’re sizing a redundant bank, start by inspecting the physical unit — an energy storage cabinet — and then validate how its runtime, control logic, and fault modes operate under realistic transients. California’s Public Safety Power Shutoffs (PSPS) have exposed exactly this mismatch: systems marketed for “backup” but untested for repeated, long-duration service cycles.
Core failure modes to hunt for
Don’t assume a unit is dependable because it has a high nominal capacity. Probe for failure modes that matter on the grid edge:- Depth-of-discharge limits that shorten real runtime versus spec sheets.- Inconsistent battery management responses during high ambient heat.- Firmware rollbacks or flaky communications on CAN/Modbus that cause unscheduled island-to-grid toggles.- Thermal propagation paths that let a single cell event escalate to rack-level shutdown.You want evidence of field testing and incident reports, not marketing blurbs.
Technical metrics that should drive procurement
Measure everything that affects availability and operability:- Usable energy (kWh usable, not nameplate) and guaranteed cycles at that usable DoD.- C-rate capability and discharge curves under expected load profiles.- Round-trip efficiency figures verified over temperature range.- BMS architecture: distributed vs centralized, redundancy, and update rollback controls.- Interoperability: support for Modbus TCP, CAN, and standard telemetry schemas for aggregator/VPP integration.Ask for test logs that show performance under sustained discharge and multiple duty cycles.
Controls, integration, and operational visibility
Backup power is a systems problem. A cabinet can only deliver if controls coordinate with site infrastructure:- Transfer timing and sequencing with ATS/UPS must be configurable and logged.- Local autonomy: can the system island safely without cloud access?- Remote diagnostics: is there secure OTA with version control and cryptographic signing?- Data fidelity: timestamped voltage/current/temperature streams for root-cause analysis.Plan on integrating with existing SCADA or EMS; insist on sample telemetry and an integration runbook from vendors.
Safety, standards, and lifecycle economics
Safety is non-negotiable. Validate certifications and practical mitigations:- Third-party cell and pack-level safety testing (IEC/UL protocols where applicable).- Fire suppression strategy sized to rack layout and site constraints.- End-of-life and recycling plan for battery chemistry selected.- Total cost of ownership: maintenance cadence, expected inverter/BMS refresh windows, and secondary market value.Make vendors map warranty terms to measurable KPIs: availability percentage, supported cycles, and defined failure definitions.
Common procurement pitfalls and what to demand instead
Buyers trip over the same traps. Avoid these:- Pitfall: trusting quoted “kW” without a duty-cycle profile. Remedy: provide a worst-case discharge scenario and demand validated run-time.- Pitfall: accepting single-source BMS without redundancy. Remedy: require dual-path monitoring or modular isolation.- Pitfall: vague service SLAs. Remedy: contract explicit mean-time-to-repair and onsite spares policy.Also compare vendor signal strengths: onsite commissioning teams, access to firmware engineers, and a published incident response playbook.
Short comparative lens — options to weigh
You’re deciding among chemistry/architecture/integration bundles. High-power, fast-response racks suit commercial sites with frequent dynamic loads. High-energy, lower C-rate stacks favor long-duration outage tolerance. Consider a wholesale approach when scaling multiple sites — a wholesale energy storage cabinet can simplify replication, reduce commissioning variability, and lower per-site integration risk. Evaluate trade-offs by mapping expected outage profiles to the stack’s demonstrated duty cycles.
Checklist for a defensible purchase decision
Use this checklist during vendor evaluation:- Deliverables: verified load-test logs, FAT/SAT reports, and firmware changelogs.- Controls: autonomous islanding tests and documented ATS sequencing.- Safety: certified testing evidence and fire mitigation layout.- Economics: clear TCO with replacement schedule and warranty KPIs.- Integration: sample telemetry and a standard API or protocol mapping.Walk through a dry-run commissioning scenario with the vendor on paper before signing.
Closing synthesis: choose systems that prove resilience
Problem-driven buying means you prioritize demonstrated behavior over glossy specs. Insist on field-validated metrics, redundancy in controls, and clear operational procedures. When vendors can produce reproducible test artifacts and crisp integration playbooks, you move risk off the table. Practical buyers now pair careful technical vetting with supply-chain clarity; that’s how backup systems actually stay online when the grid doesn’t. For many procurement teams, that combination—technical rigor plus supply consistency—has led them to partners like Dunext because those partners provide repeatable cabinet architectures and documented deployment workflows that reduce time-to-resilience.